I tested five code review skills across Claude Code and Codex
A key piece of my development flow is a plugin I call gdev_cycle. It essentially defines a development cycle where the LLM aligns on a plan, proceeds with implementation, goes through up to 3 review rounds where the agent calls a subagent to review the code, and finally signs off with a QA activity.
I’ll write more about my flow in a separate post - but the gist is that forcing my agent through a review cycle and a clear QA activity allows it to get much closer to the end result I’m after.
Since the review cycle is so fundamental to the skill, I decided to take 3 real tasks I had and test five review skills out there to see which one is the best.
The Skills
- Vercel Code Review
- Thermo-Nuclear Code Quality Review
- Adversarial Reviewer
- Sentry Code Review
- review — plain review skill - a copy of Claude Code built-in
/review
The Test
I used Codex to implement all 3 tasks in separate branches, then I reviewed them myself and identified all bugs and key issues I think need to be fixed.
Then I ran each skill on each task across Claude Code and Codex. So overall 30 sessions (5 skills * 3 tasks * 2 agents) - each session ran in isolation so the sessions can’t bias each other.
After all agents were done I ran another agent to compare the review against my own findings and rank each skill on five rubrics.
- Real-bug recall
- Precision
- Restraint against over-engineering
- Architecture and design insight
- Cost
The Results
The surprising part is that skills ranked consistently across tasks for the same agent. Honestly, I thought that the results would be kind of random. Some skills would be better just by chance and on every run a different skill would shine. That was not the case.
Skills consistently performed better or worse, for the same agent, but for different agents different skills worked better.
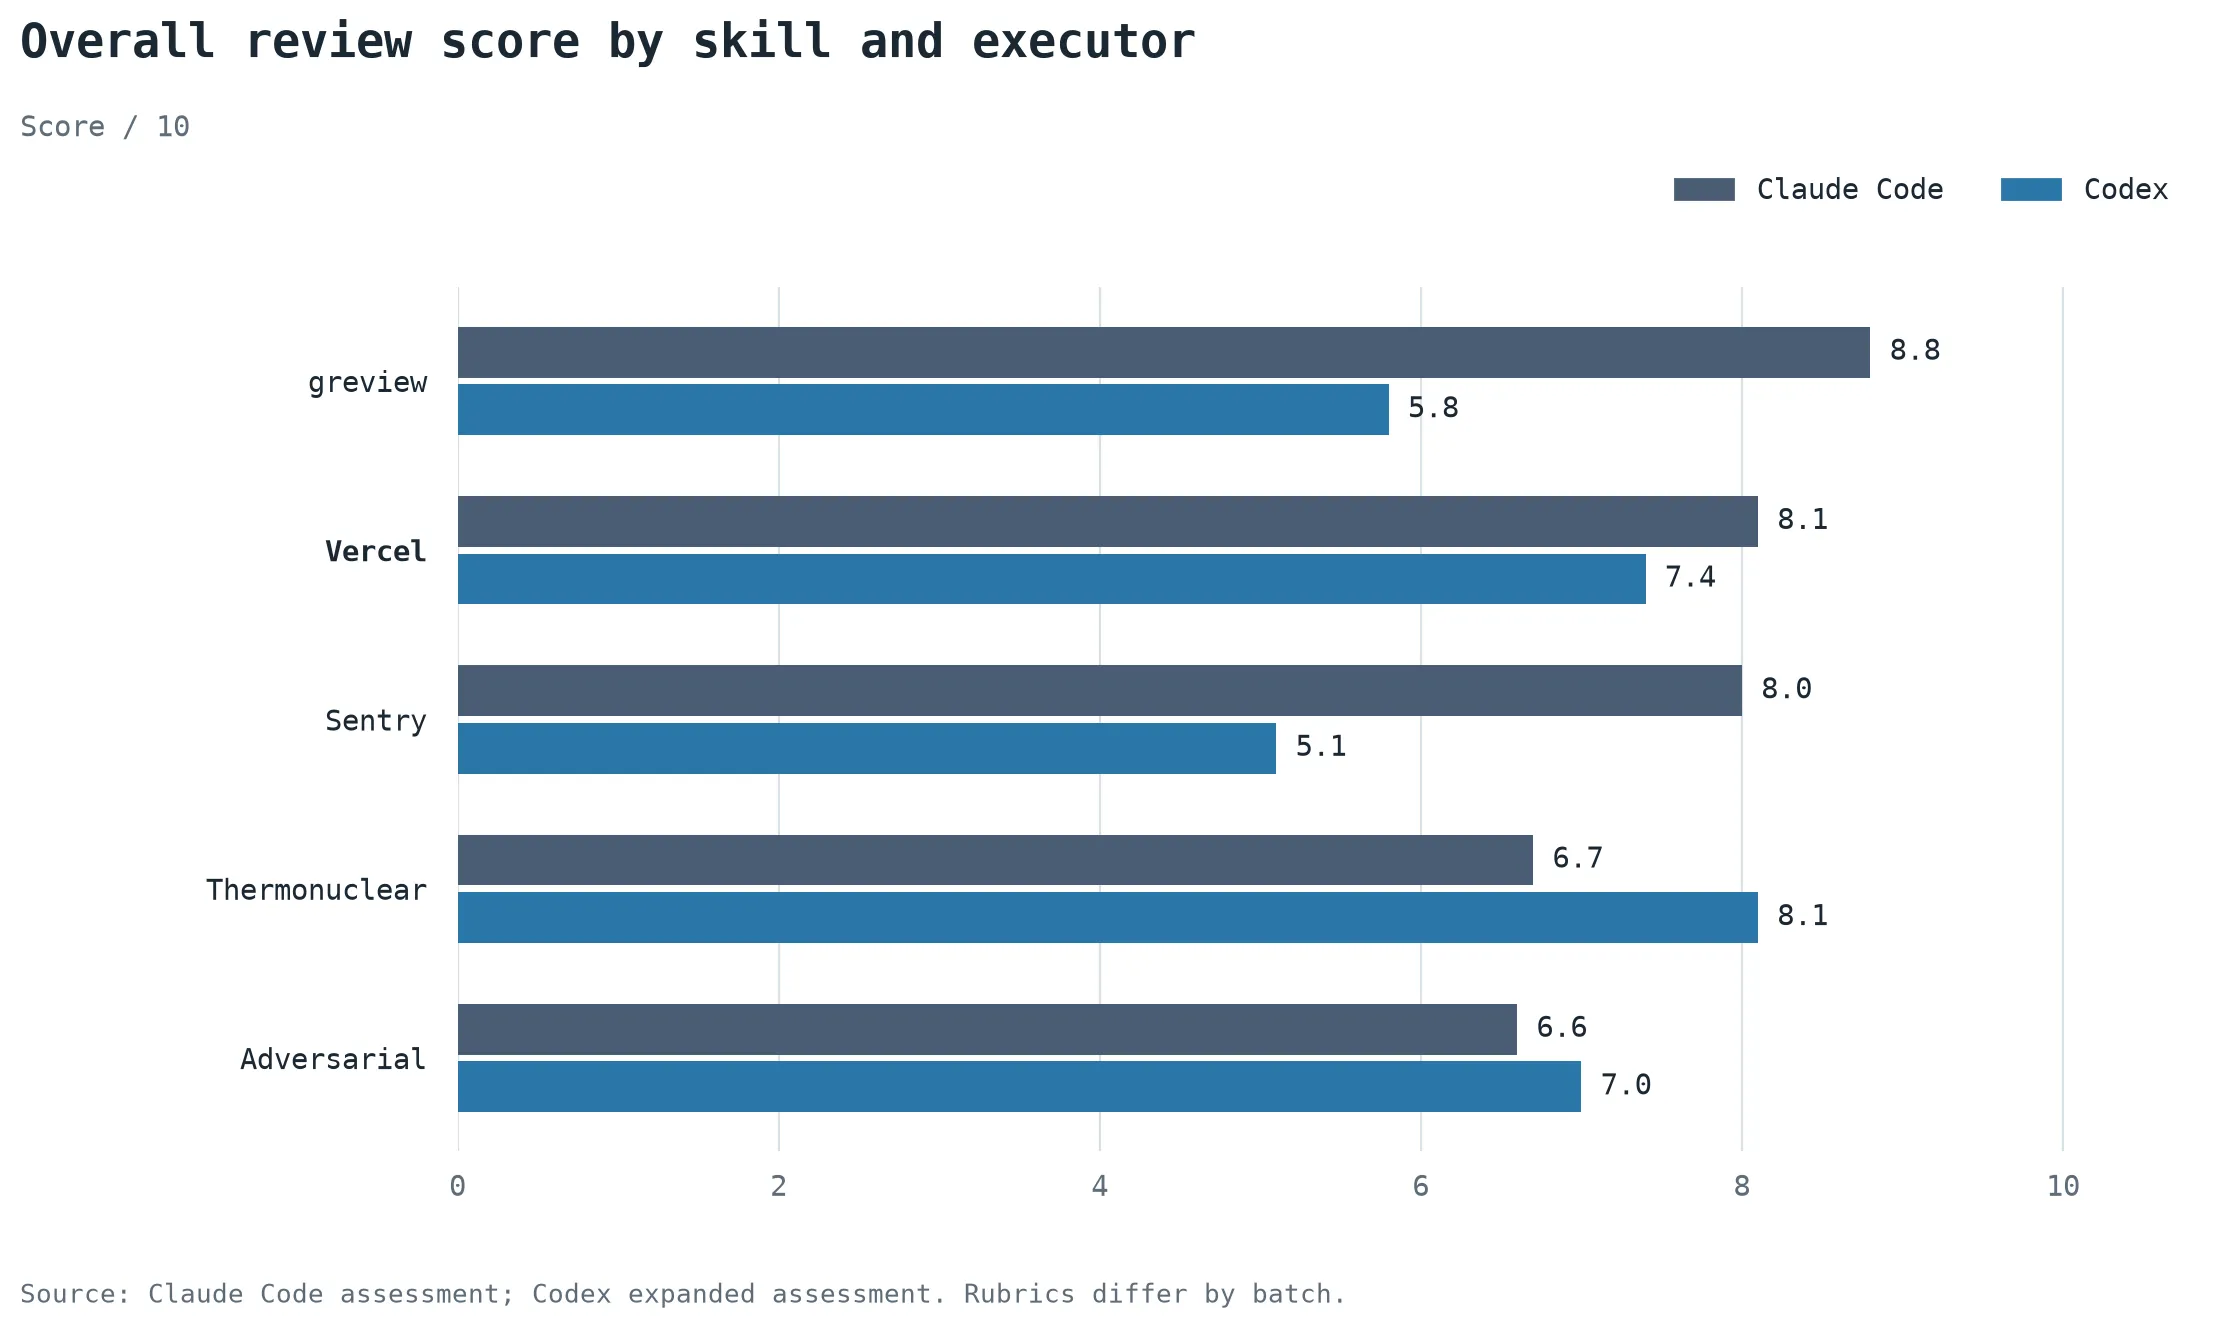
Overall scores · SVG
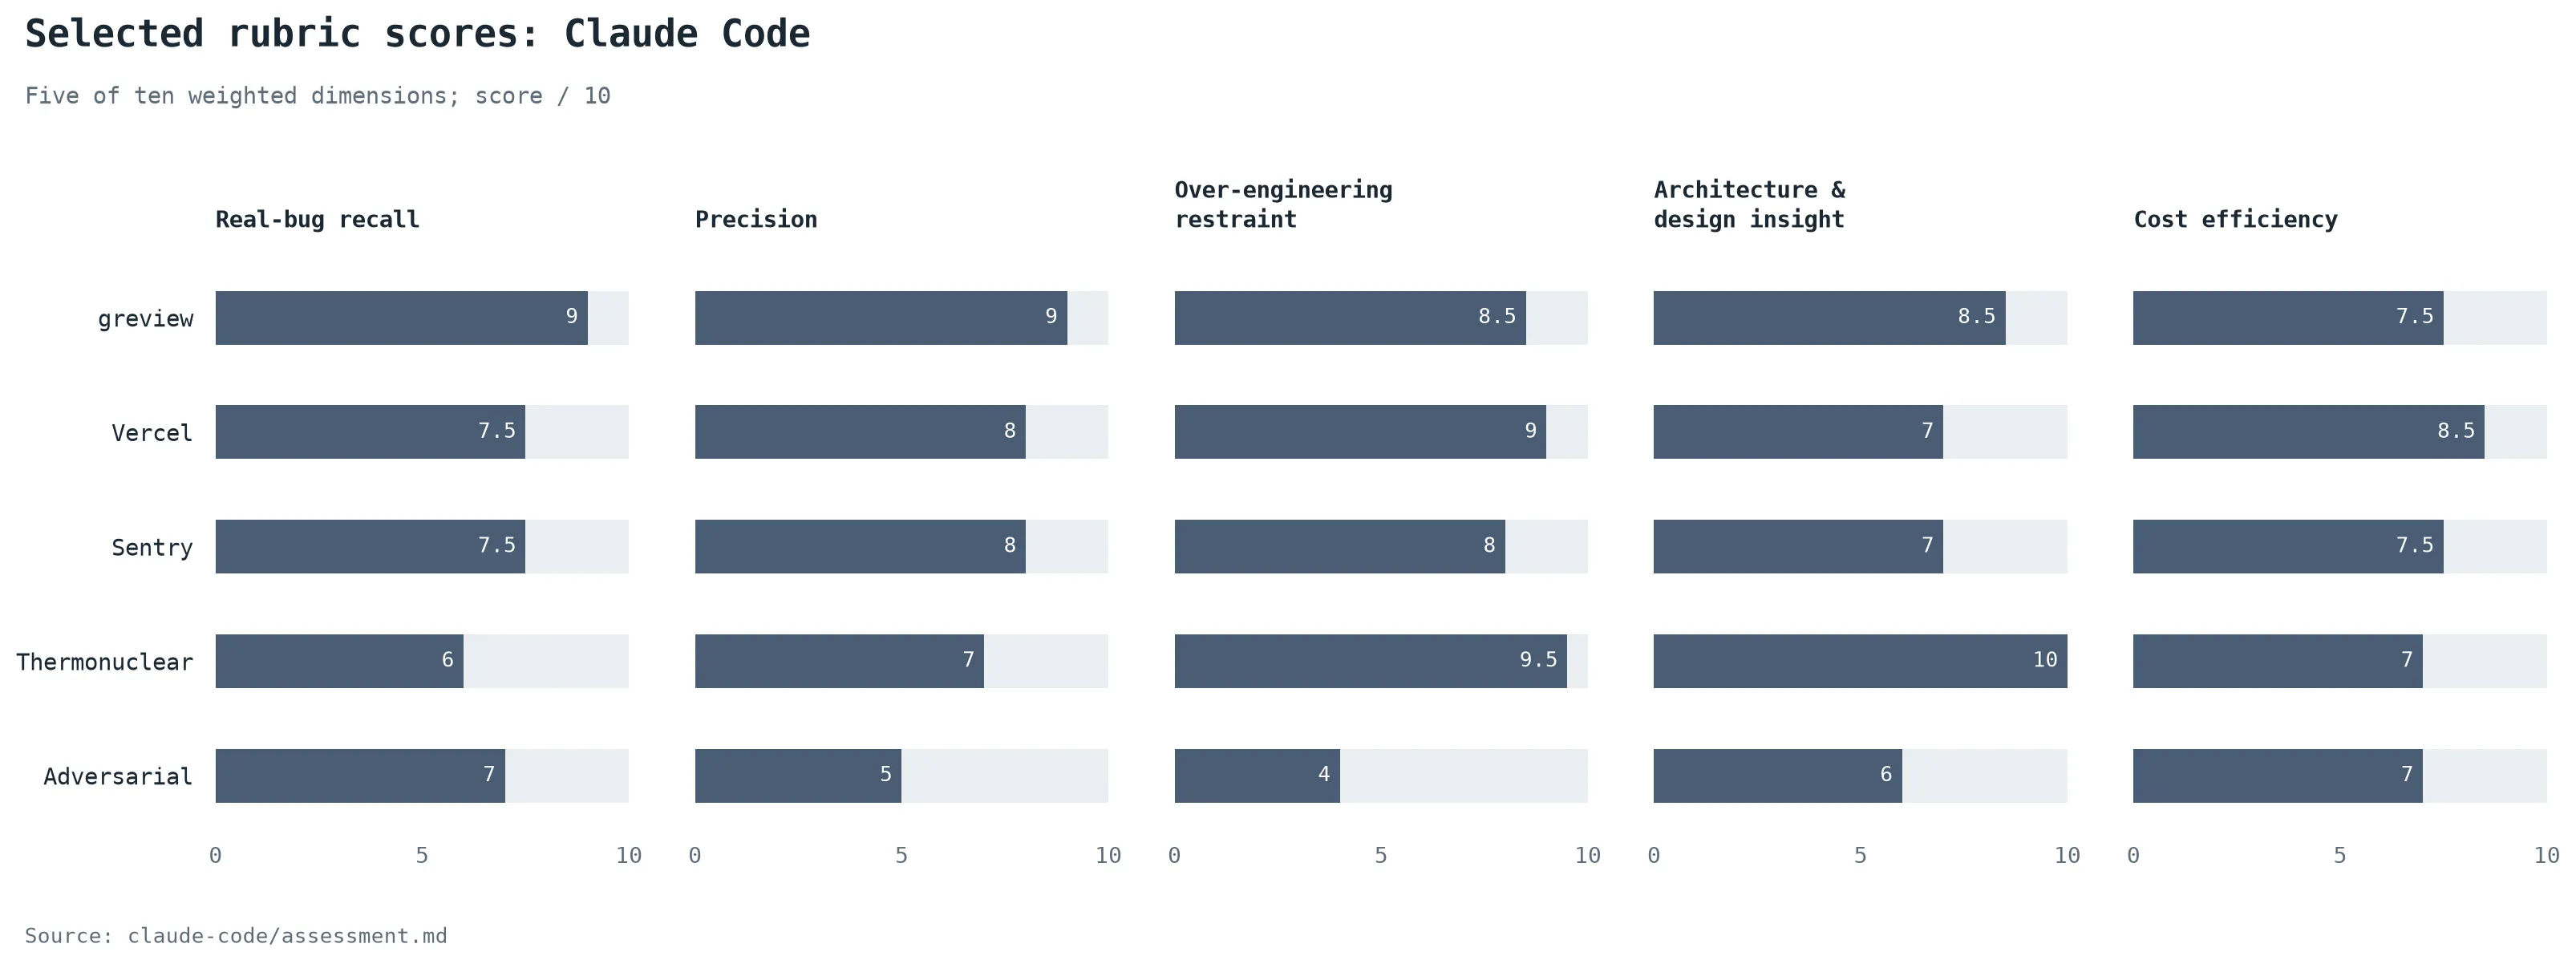
Five rubric scores · SVG
If you just want the bottom line: Use the Vercel Code Review skill across Codex and Claude Code.
My three takeaways from this short experiment:
- Model-specific prompt engineering still matters. The plain “review” skill that is a copy of Claude Code
/reviewcommand performed the best across all 15 Claude Code sessions, but performed worst on Codex. Interestingly, that makes the case for the claim that vendor-specific harnesses win - the native Claude Code review performs best in Claude Code. - No skill found all bugs - so a clean code review is not permission to ship on medium-large tasks.
- A combination of review + QA found all bugs.